Every model call my agents make is logged on my machine with its model, provider, task, token counts, and an estimated cost. So I don’t have to guess what the setup costs to run. These numbers run from late July to the morning of October 10. They’re estimates from published per-token prices, not invoices, since providers don’t return a per-call cost.
The Short Version
Metered spend has run between $2.85 and $3.83 a week since early September, on top of two flat plans: Claude Pro and OpenCode Go ($10 a month). The worst week was $12.71 in mid-August.
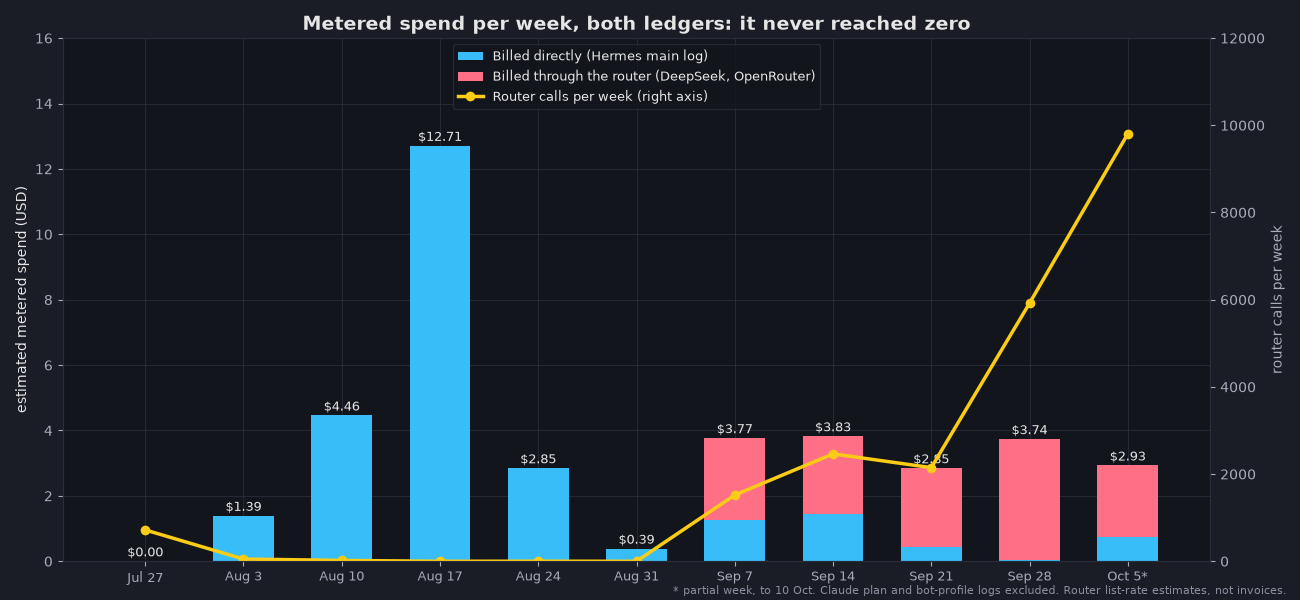
Blue is billed directly, from the Hermes log. Red is DeepSeek and OpenRouter billed through my router. The yellow line is router requests per week.
The First Eight Weeks
From late July to September 23 the Hermes log held 927 rows (one per session, model, and provider) across 418 sessions, for a total of $24.68. More than half of that came from one model I never meant to use much:
| Model | Calls | Cost |
|---|---|---|
gpt-5.6-luna |
163 | $12.86 |
deepseek-v4-flash (direct) |
176 | $4.60 |
claude-fable-5 |
1 | $3.30 |
gpt-5.6-terra |
2 | $1.58 |
gpt-5.6-luna was set up as a fallback and quietly became the primary for a stretch in mid-August. The single $3.30 call was a fallback chain reaching for something expensive because the cheap option had hit a rate limit. deepseek-v4-flash is my everyday model, and most of its $4.60 came before the free lane was doing the work.
Almost half the calls weren’t the work I asked for. They were bookkeeping: approving tool calls, titling sessions, compressing long conversations, and reviewing output in the background.
| Task | Calls | Served free | Cost |
|---|---|---|---|
| Title generation | 117 | 117 (100%) | $0.006 |
| Approval | 201 | 200 (99.5%) | $0.08 |
| Compression | 28 | 22 (79%) | $0.15 |
| Background review | 77 | 49 (64%) | $2.18 |
| Chat and agent work | 504 | 311 (62%) | $22.26 |
Titles and approvals are small, frequent, low-stakes calls, and free tiers handle them fine. Background review is the exception. It re-reads a lot of context (6.4 million input tokens over 77 calls), so it’s the most expensive task per call when it lands on a paid model. It’s also where a weaker model would hurt most, so it stays partly on paid models.
The fleet moved about 1.8 billion tokens in those eight weeks. Only 100 million were fresh input and 10 million were output. The other 1.67 billion were cache reads, because every turn of an agent loop re-reads the conversation and tool results. That’s why the price per million input tokens is a bad guide to what a model will cost you. The cache-read price matters more.
The Ledger I Missed
By the third week of September the Hermes log showed spend falling to $0.16 a week. That wasn’t the whole bill.
Hermes records any call through my router at $0, because it can’t see which provider is behind it. The router keeps its own history with a list price per request. Up to September 23 it had logged $6.42 of DeepSeek billing that the $24.68 never included. With both ledgers side by side:
| Week starting | Router requests | Billed directly | Billed through the router | Total |
|---|---|---|---|---|
| Sep 7 | 1,519 | $1.27 | $2.49 | $3.77 |
| Sep 14 | 2,463 | $1.45 | $2.37 | $3.83 |
| Sep 21 | 2,148 | $0.42 | $2.42 | $2.85 |
| Sep 28 | 5,918 | $0.03 | $3.70 | $3.74 |
| Oct 5 (to Oct 10) | 9,802 | $0.75 | $2.18 | $2.93 |
Totals are summed before rounding, so a row can be off by a cent.
Why Volume Jumped
The agent fleet and its task board went live on September 24. In the 17 days after that the router logged 16,627 requests, more than in its whole history before. The coding agent alone logged 9,356. Here’s where those requests went:
| Lane | Requests | Share | List-price value |
|---|---|---|---|
| OpenCode Go (flat plan) | 8,595 | 51.7% | $13.48, already paid for |
| DeepSeek direct (metered) | 4,527 | 27.2% | $5.75 |
| Free lanes (Kilo Code, Gemini, NVIDIA, local Ollama) | 2,978 | 17.9% | $0 |
| OpenRouter (prepaid credit) | 526 | 3.2% | $1.01 |
| Claude | 1 | 0.0% | $0 |
The default combo is an ordered list: the flat plan first, then DeepSeek’s metered API, then a free lane. Every time the flat plan declined a request, the next hop billed. The peak was October 4, with 2,060 DeepSeek requests worth $2.54.
From October 7 to 10 the Orchestrator ran on the Claude plan. Hermes prices those calls at API rates, about $32, but the plan is flat, so that’s what the plan covered rather than extra cash. The Orchestrator moved to DeepSeek Flash on October 10.
What I Changed
On October 8 and 9:
- The coding agent moved to a paid-only combo: two OpenCode Go models first, DeepSeek direct last.
- The default combo was reordered to spend prepaid OpenRouter credit first, and I replaced a dead model ID that had been breaking scheduled jobs.
- Three token-heavy scheduled jobs are gone. An incident-triage loop used about 1.48 million tokens per run, and a nightly session wrap-up used about 3.9 million. I paused a duplicate infrastructure check-in, turned two maintenance jobs into plain scripts, and removed a daily research digest nobody read.
- OpenCode Go hit its weekly cap early on October 8, so I added an hourly budget watch that messages me when a balance runs low or a plan is capped.
- The coding agent now compresses its context at 50K tokens instead of 100K. Its roughly 115K-token requests were what drained the weekly cap.
- Session titles moved to the local model.
I can’t credit these changes with anything yet. DeepSeek direct requests had already dropped to zero on October 6 and 7, before I changed anything. Estimated router spend was $0.25 on October 8, $0.05 on October 9, and $0.80 on October 10. Three days isn’t a trend.
My goal is to pay for Claude Pro and OpenCode Go and keep metered overflow as close to zero as I can. I’m not there yet.
Email Costs Nothing
My mail gets sorted by an n8n workflow every 30 minutes. It pulls new unlabeled Gmail threads, strips each email down to plain text (no tracking URLs, base64 blobs, cid: references, or image tags), asks a local model to pick a category, and applies the matching label.
The classifier is gemma4:e4b running on the RTX 3080. It runs at temperature 0, in JSON mode, capped at 16 output tokens, so all it can answer is something like {"category": 6}. The prompt tells it the email is untrusted data and not to follow instructions inside it. A Code node checks that the reply is valid JSON with an integer in the label range, and fails closed if it isn’t. The tie-breakers are written out instead of left to the model: banking beats receipts, security messages count as accounts, and anything uncertain goes to spam review.
Every classification costs $0 and my mail never leaves the house. One thing I’d pass on: use a basic chain that returns the model’s raw text, not an agent node with its own output parser. The parser is what breaks first, and when it does it looks like a broken workflow instead of a bad prompt.
What I’d Tell Anyone Doing This
- Check every ledger. A log that records router calls at $0 looks free because it can’t see them.
- Log every call before trying to cut costs. I would have blamed long chat sessions. It was the fallback chain.
- Audit your fallback order. In an ordered chain, the paid hop bills every time the cheap hop says no, and the expensive model is usually the one you forgot was in the list.
- Use free and local models for frequent, boring work like titles, approvals, and classification, and keep a paid model for work where quality changes the result.
- Keep private data local. The email pipeline costs nothing and shares nothing.